CTPN and the First Step: Finding Equation Regions Before OCR
Why Equation OCR Starts with Region Proposals
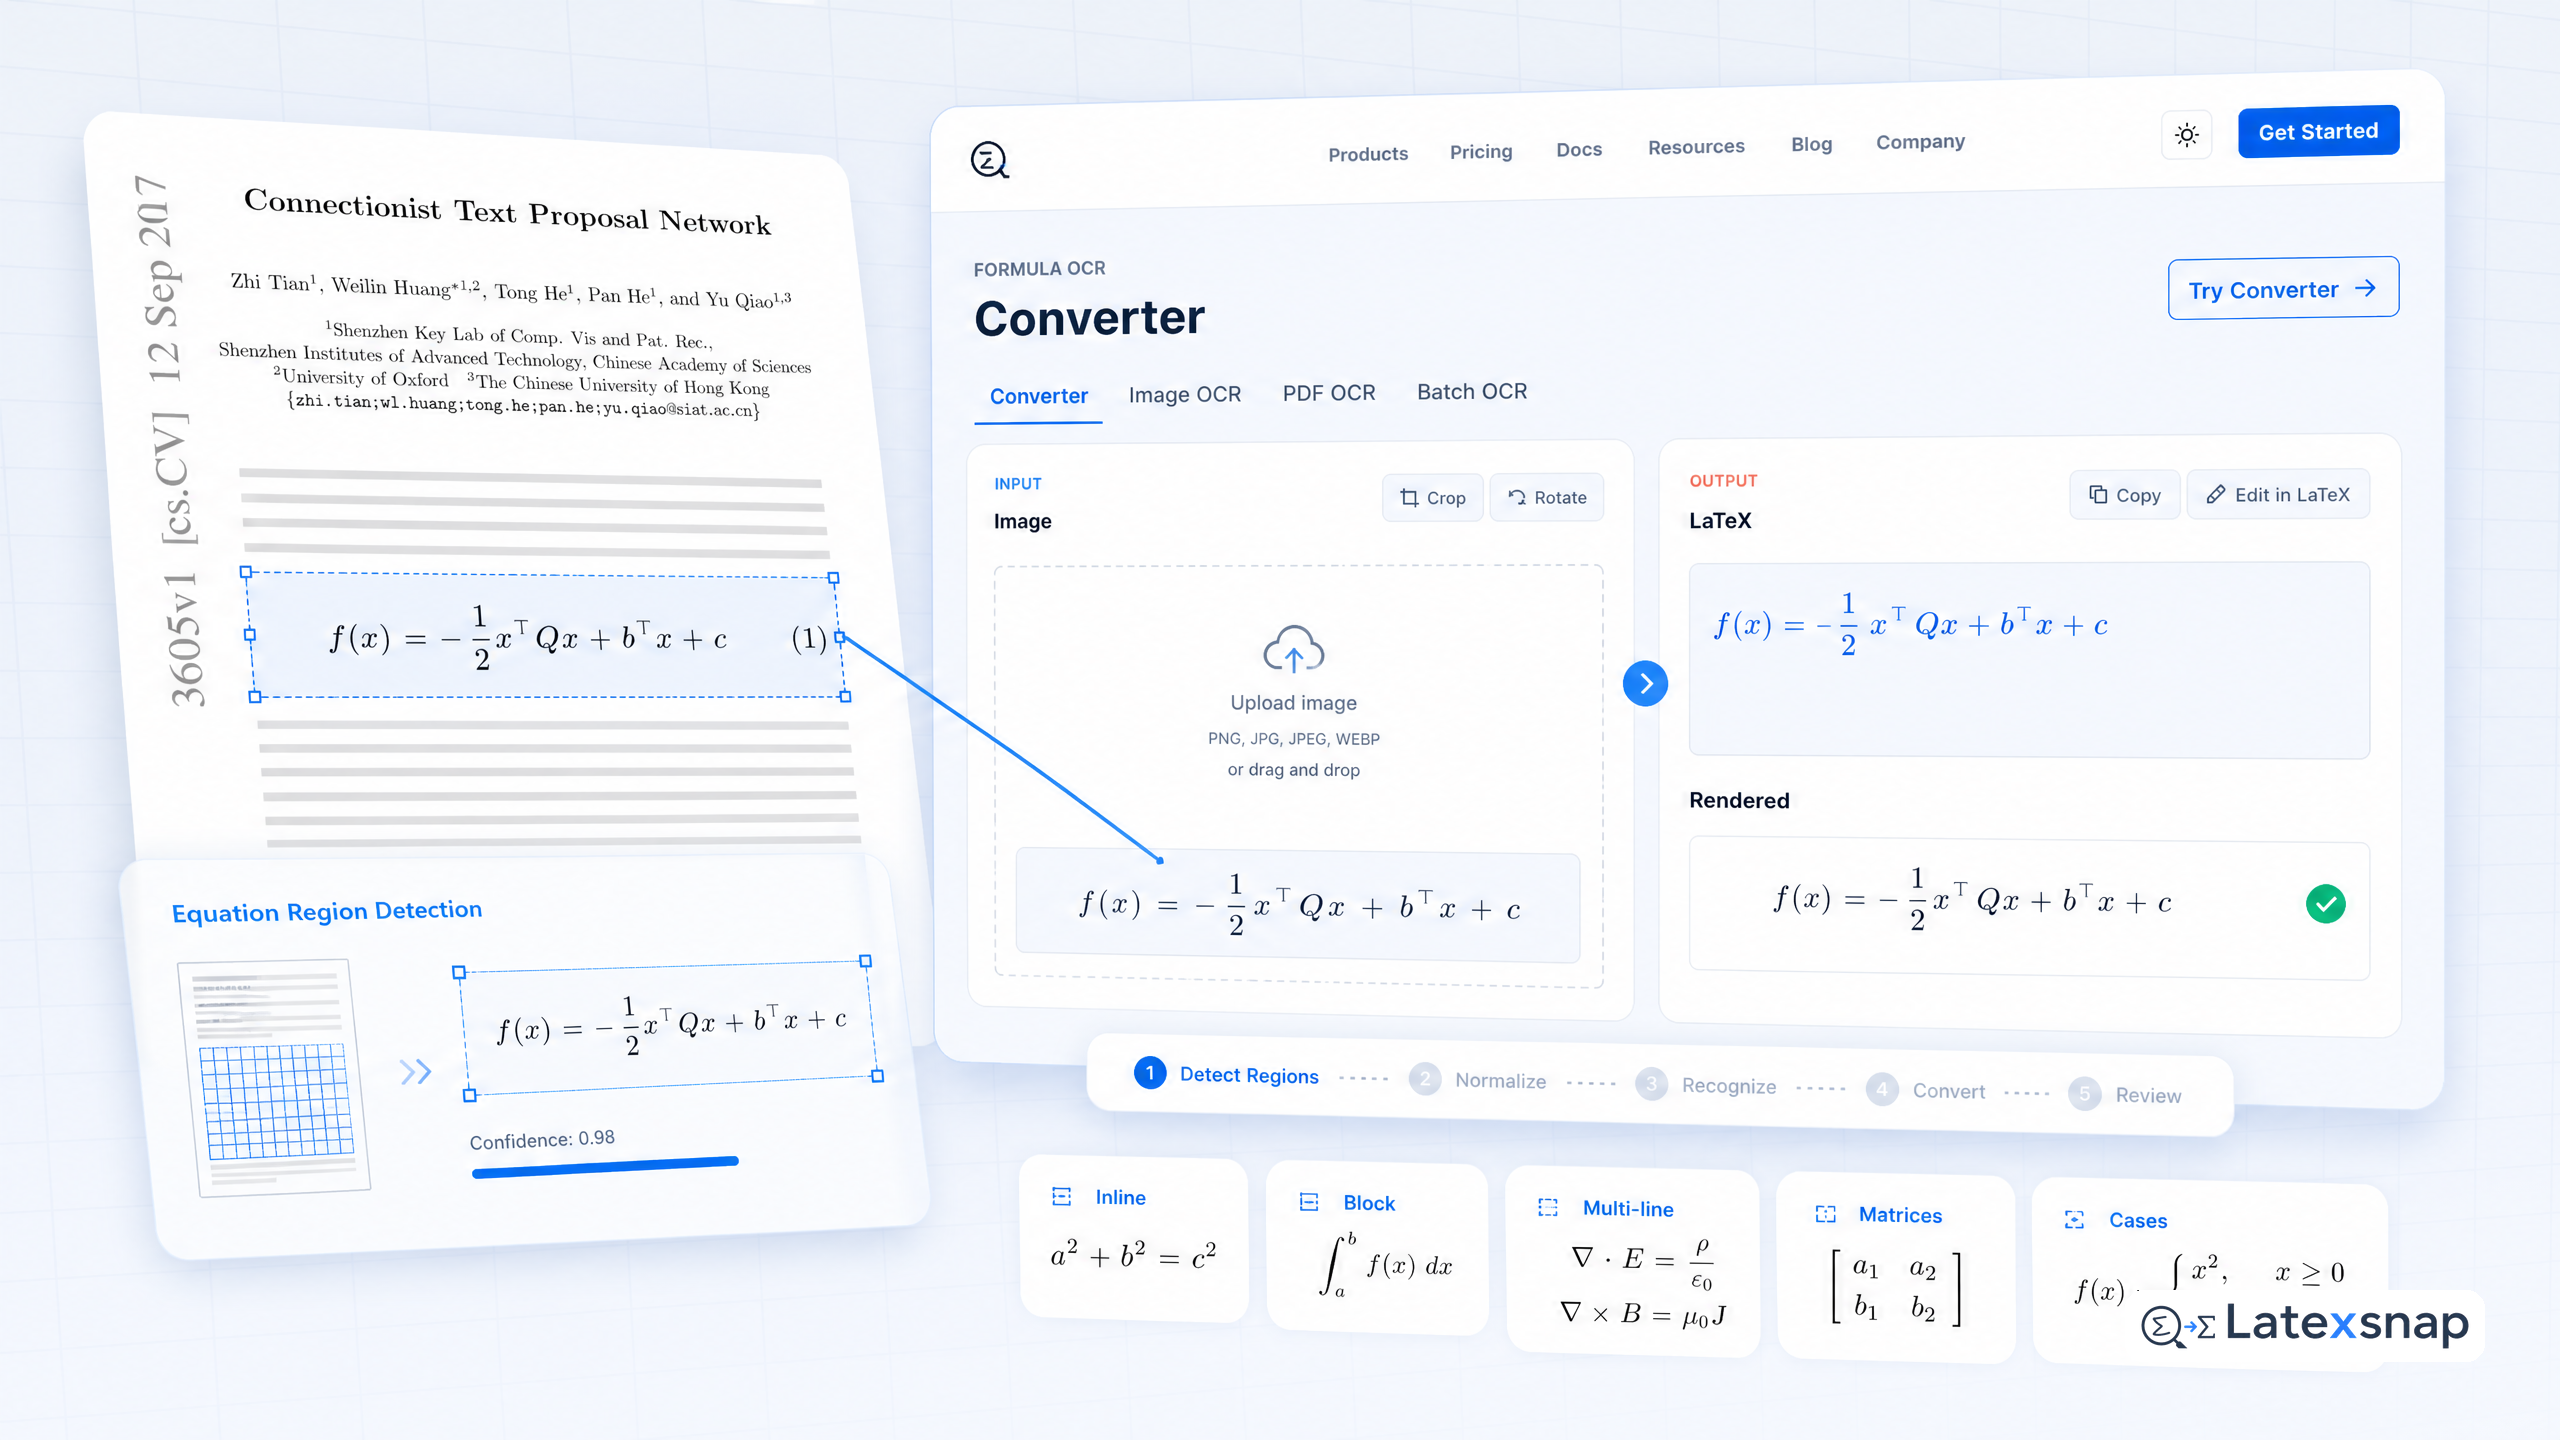
When you upload an image of a formula to LatexSnap, the system doesn't immediately run a character recognizer. It first asks a simpler question: where are the equation regions? This step, called equation region detection, is the foundation of reliable formula OCR. Without it, the system risks misaligning tokens, splitting long expressions incorrectly, or missing nested structures entirely. For a related next step on equation mask detection, see DBNet and Cleaner Equation Masks for Faster Formula Capture.
LatexSnap uses a two-stage pipeline. The first stage identifies bounding boxes that likely contain math. The second stage extracts those boxes and runs a transformer-based model to convert them into LaTeX. This separation mirrors how human editors approach complex formulas: first locate the relevant parts, then interpret them.
The Problem with Naive Bounding Boxes
Early approaches to formula detection relied on fixed-size crops or simple thresholding. These methods fail when equations span multiple lines, contain nested braces, or include graphical elements like matrices or integrals. A naive crop might cut off a summation symbol or misidentify a fraction bar as a line break. If you want to compare this with another practical angle, CRAFT and Character-Level Clues for Math Symbol Localization covers math symbol localization in more detail.
LatexSnap avoids these pitfalls by training a detection model on annotated datasets of academic papers. The model learns to distinguish between text, figures, and mathematical expressions, even when they overlap or appear in unusual layouts. This capability is critical for handling real-world documents where formulas are rarely isolated. When the document pipeline gets more complex, Nougat and Academic Paper OCR for Equation-Heavy Documents gives more context on academic paper OCR.
How CTPN-Inspired Models Work
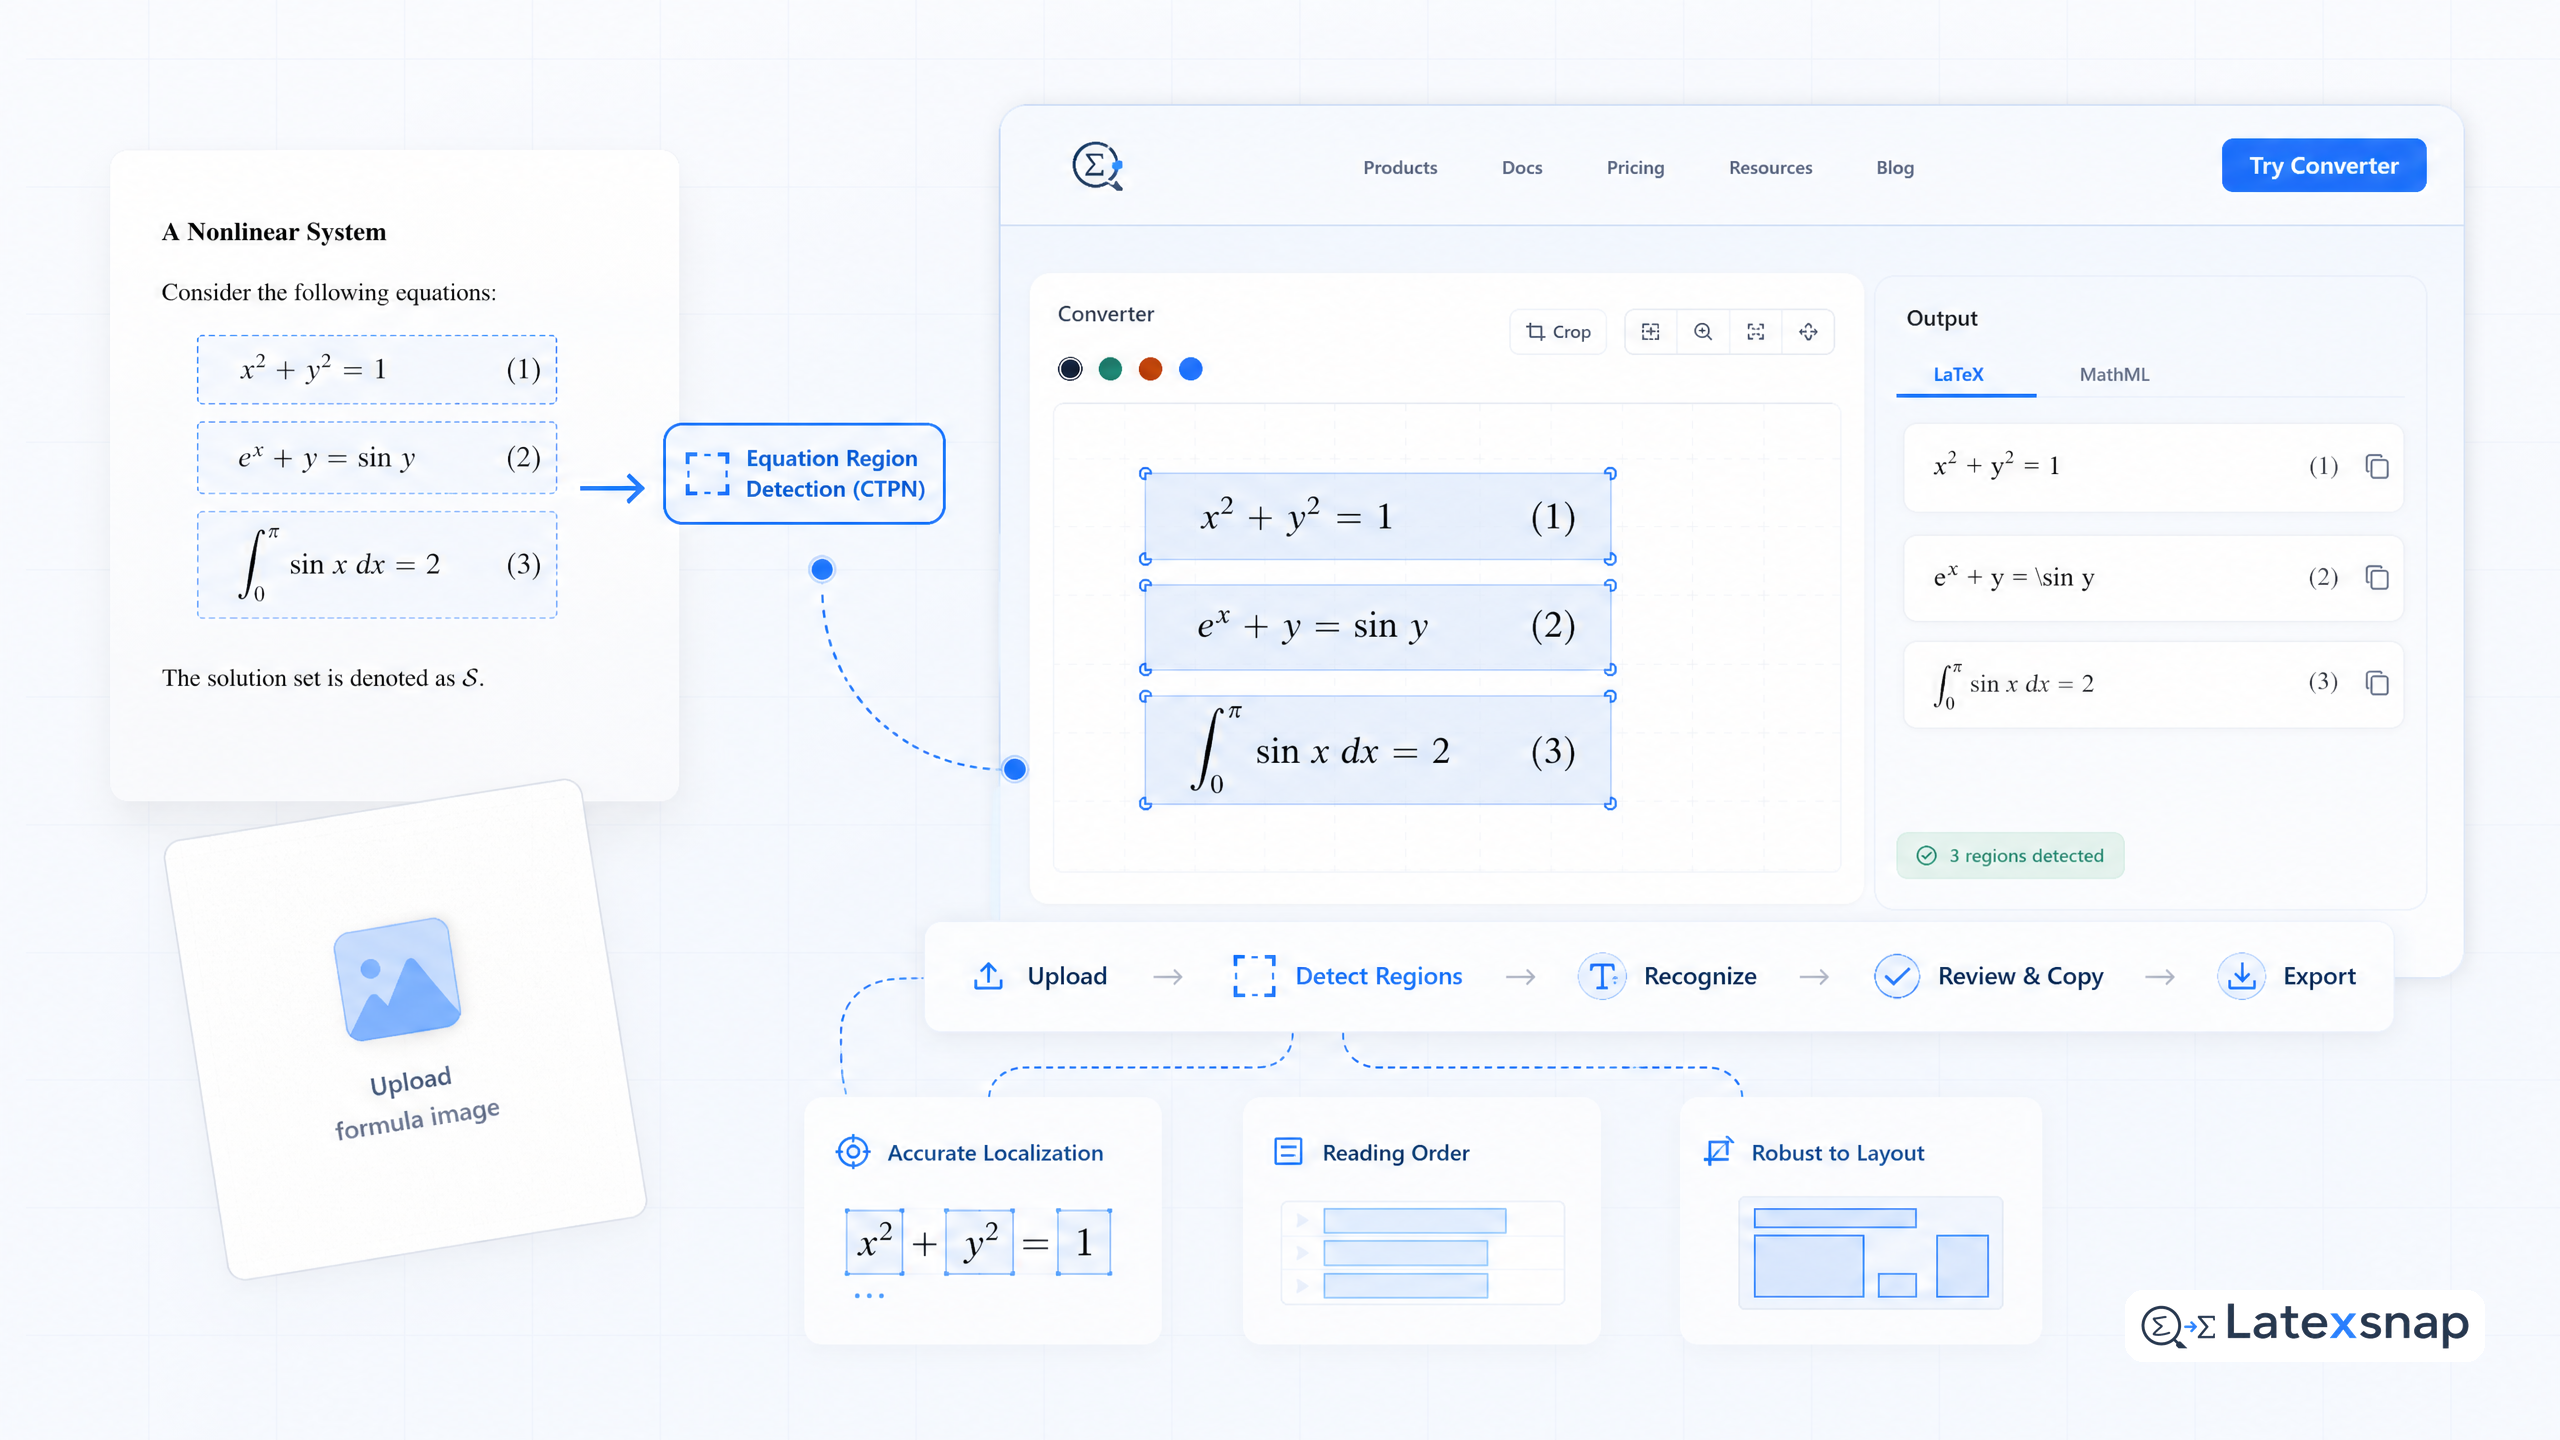
The Connectionist Text Proposal Network (CTPN) introduced a novel way to generate text proposals without relying on pre-defined regions. Instead of using selective search or hand-crafted anchors, CTPN applies a convolutional neural network directly to the image to produce overlapping candidate boxes. Each box is then classified as text or non-text using a softmax layer.
LatexSnap adapts this idea for equations. Rather than detecting individual characters, the model predicts regions that likely contain complete expressions. These proposals are then refined using non-maximum suppression to eliminate duplicates and improve precision. The result is a set of high-confidence bounding boxes that serve as input to the transcription model.
Why Region Detection Matters for LaTeX Output
Equations in LaTeX are not just sequences of symbols-they are structured trees of commands and arguments. A poorly detected region can lead to malformed output. For example, if a fraction is split across two crops, the parser may generate invalid syntax or misinterpret the numerator and denominator.
LatexSnap's region detection ensures that each crop contains a coherent mathematical unit. This allows the downstream model to focus on accurate tokenization and structure prediction. In practice, this means fewer manual corrections and more consistent output across different document types.
Practical Tips for Better OCR Results
To maximize the accuracy of your formula OCR, consider the following: For teams extending this workflow, CTC and the Problem of Reading Unsegmented Formula Images is a natural follow-up for CTC formula OCR.
- Crop quality matters: High-resolution images with clear contrast yield better detection results. Avoid skewed or low-contrast scans.
- Ambiguous symbols: Some symbols like
+,-, and=can appear in both text and math contexts. LatexSnap uses context to disambiguate, but unusual fonts or handwriting may still cause errors. - LaTeX structure: Nested structures like integrals, sums, and matrices require precise region boundaries. If a formula spans multiple lines, ensure the entire block is included in one crop.
- Manual review: Even with advanced detection, some formulas may need adjustment. LatexSnap provides an editor where you can refine the output before finalizing.
Final Thoughts
Equation region detection is not just a preprocessing step-it's a critical component of any robust formula OCR system. By identifying meaningful regions before token recognition, models like LatexSnap can achieve higher accuracy and better structural fidelity. As detection algorithms continue to improve, so too will the quality of automated LaTeX generation. A useful companion workflow is EAST and Better Crop Boundaries for Equation Screenshots, especially when text detection crop boundaries becomes part of the review process.
If you're building or evaluating a formula OCR workflow, prioritize region detection as much as transcription accuracy. The difference between a usable and unusable output often comes down to this first step.
Convert formulas faster
Turn screenshots, handwriting, and PDFs into editable LaTeX.